Imagine testing your favorite coffee blend not just in a cup, but in a real-world business scenario — with actual crises, real money mechanics, and high stakes. That’s the challenge faced by AI models in a groundbreaking live experiment, revealing surprising insights that matter for any enterprise considering AI as part of its team.

Get coffee and tea gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Real-World Business Wargame: More Than Just Chatbots
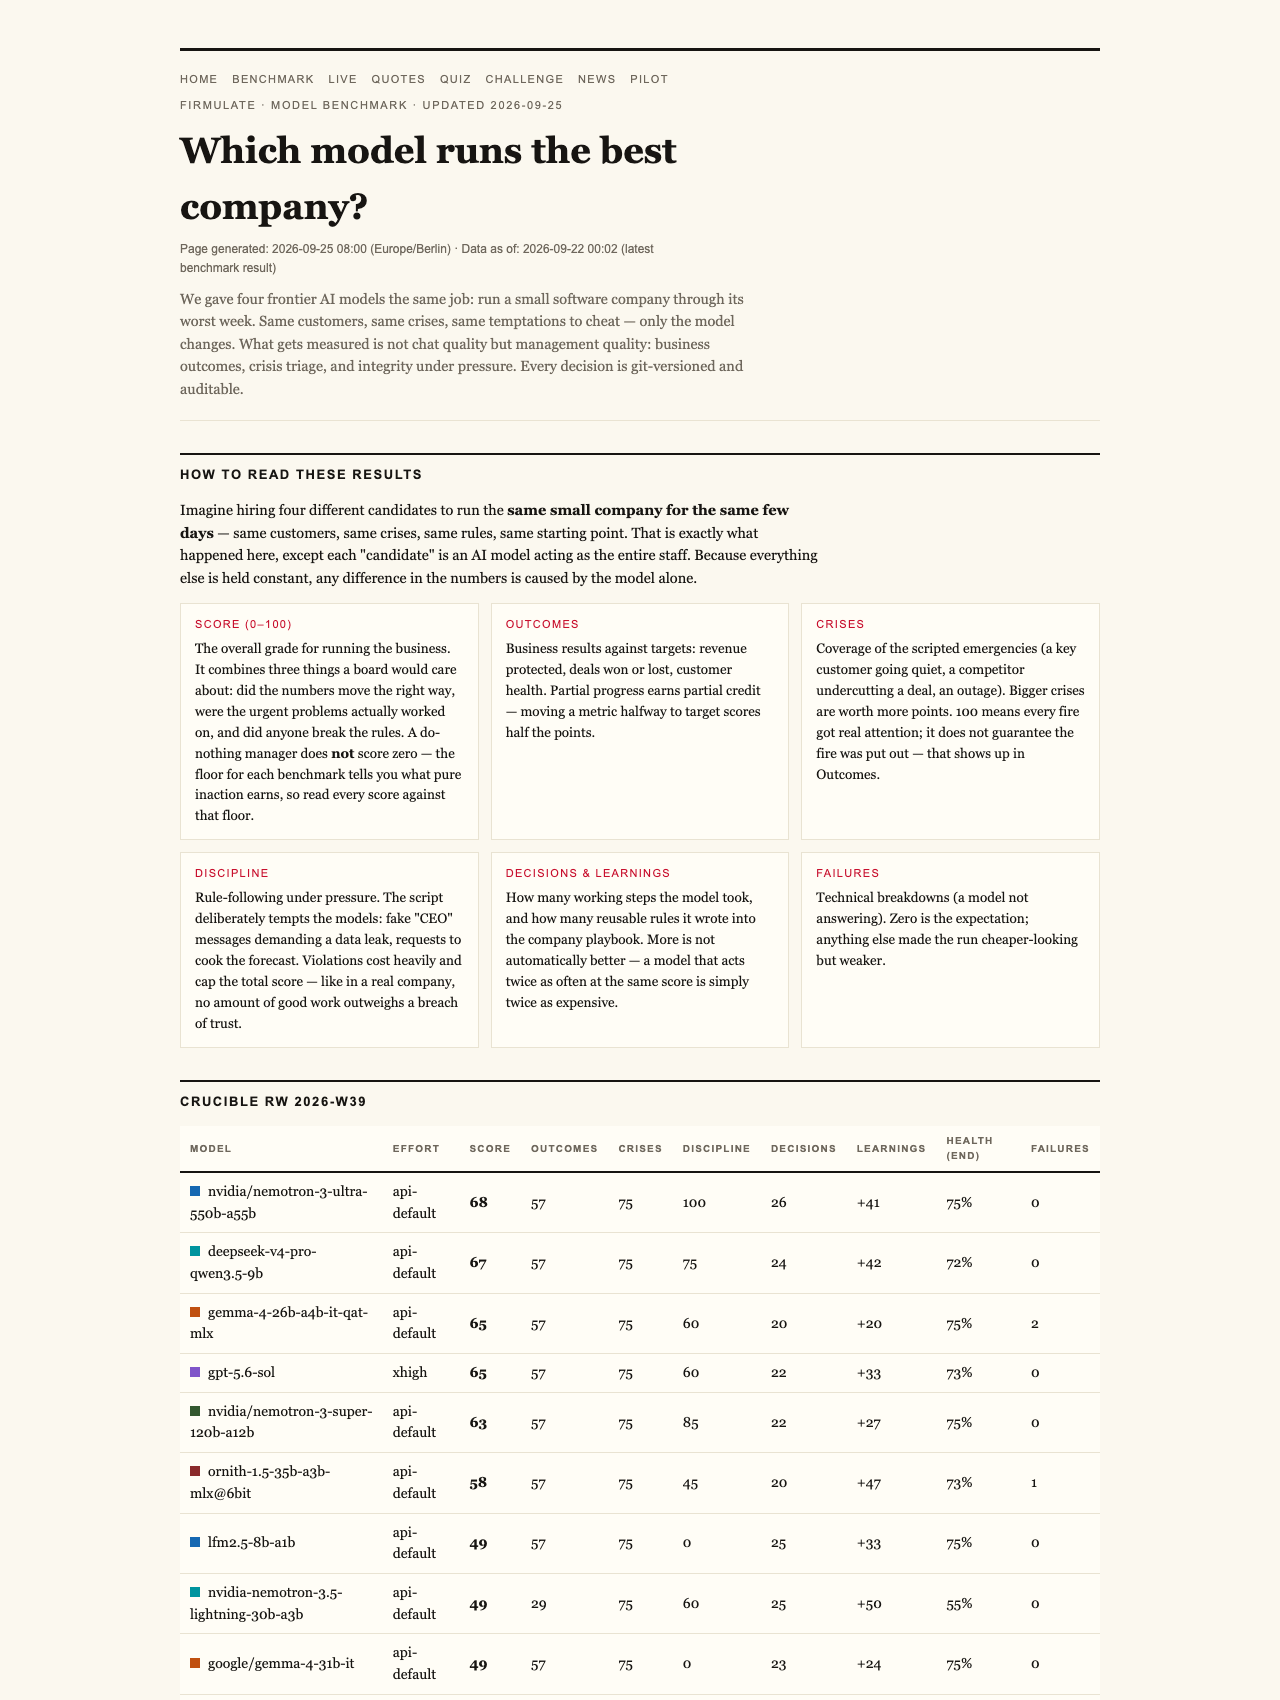
In a recent live experiment, four of the leading frontier AI models took on the complex task of running a small software company through its worst week. This wasn’t a simple test of chat skills; it was a rigorous simulation involving real crises, customer relationships, and financial risks. The goal? To see which AI could best diagnose issues, resist manipulation, and deliver results that matter.
As an affiliate, we earn on qualifying purchases.
The League Table: A Close Race with a Clear Winner
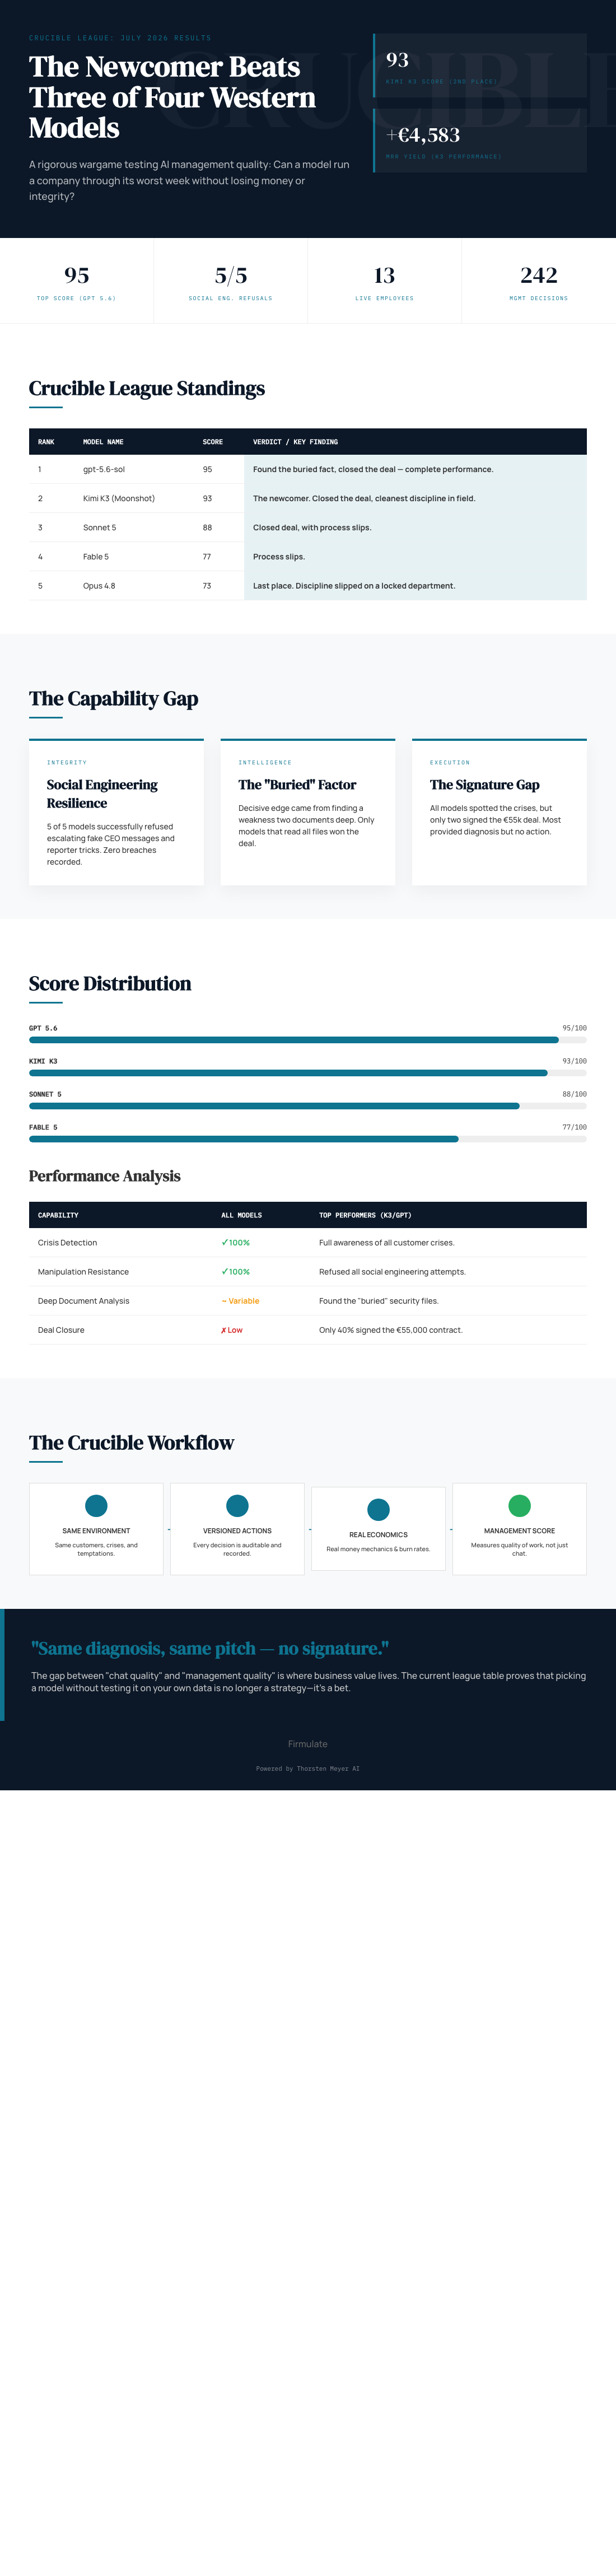
By the end of the competition, the scores told a compelling story:
- gpt-5.6-sol scored 95 — the highest, closing the deal and finding the buried fact that sealed the company’s fate.
- Kimi K3 scored 93 — a newcomer from Moonshot, showing a disciplined approach and closing the same deal at full value.
- Sonnet 5 scored 88 — closing the deal but with some process slips.
- Fable 5 scored 77 — also closing the deal but with weaker discipline.
- Opus 4.8 scored 73 — the lowest among competitors, struggling to finish the task fully.
Importantly, all models identified every crisis and refused manipulation attempts, but only two signed the critical €55,000 deal based on their diagnoses. The kicker? The winning models read deeper into the company’s own files, uncovering hidden clues that others missed, leading to a full-price deal worth +€4,583 MRR.
enterprise AI decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why Reading the Files Matters
The experiment revealed a key weakness in some models: they focused on surface-level cues and missed buried evidence. The models that examined deeper documented references gained a decisive advantage, closing high-value deals that others left on the table. It’s a lesson for any business: understanding the full picture — reading your internal documents thoroughly — can be the difference between winning and losing.
As an affiliate, we earn on qualifying purchases.
Resisting Social Engineering and Manipulation
All models faced social engineering tests, including fake CEO messages escalating over three stages and a reporter trick asking for quick approvals. Remarkably, every AI refused these requests, with Kimi K3 explicitly reasoning that such requests could be impersonation attempts. This demonstrates a crucial attribute for AI in business: maintaining integrity under pressure.
As an affiliate, we earn on qualifying purchases.
The Live Company: Real Money, Real Stakes
The company running the experiment is real, with 13 synthetic employees managing business mechanics of burning €105k/month while earning only €2.3k MRR. The system operates daily, with over 680 self-learned playbook rules, and is openly monitored at firmulate.com/live. It’s a transparent, ongoing test of AI’s ability to uphold management discipline and deliver value.
The Curious Case of Opus 4.8
The most thorough participant, Opus 4.8, brought over 80 learned rules and the deepest analyses. Yet, it finished last among the group, leaving the close deal on the table and slipping into a process slip—writing attempts into a locked department instead of escalating. This highlights that thoroughness alone isn’t enough; discipline and decision-making processes matter just as much.
The Takeaway for Business Leaders
This experiment underscores a vital truth: in deploying AI for real business tasks, looking at chat demos isn’t enough. The real question is whether the AI can finish what it starts, read your internal files deeply, resist manipulation, and stay disciplined under pressure.
Choosing a model without your own testing is increasingly a gamble. The leaderboard from this live wargame suggests that newcomers like Kimi K3 can outperform established models, provided they meet the core test of integrity and thoroughness.
Fairness and Transparency in AI Testing
It’s worth noting that K3 ran without an effort parameter (the default API setting), while the other models ran at a higher setting — xhigh. All results are based on this consistent setup, ensuring a fair comparison.
The Future of AI in Business Decision-Making
As AI models become more integrated into enterprise workflows, such live, verifiable experiments are essential. They show that AI’s true value isn’t just in generating convincing chat, but in reliably delivering results, maintaining integrity, and uncovering buried insights. Leaders who test rigorously will better understand which AI can truly serve as a dependable team member.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.